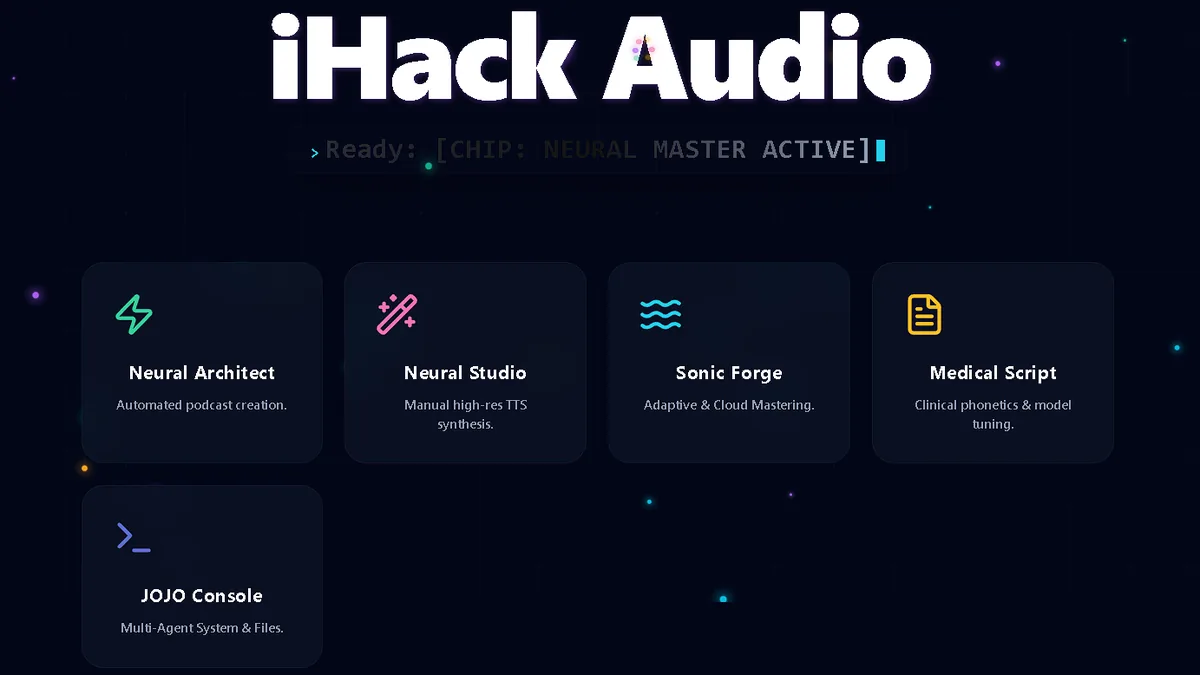
iHack Audio — The Ecosystem
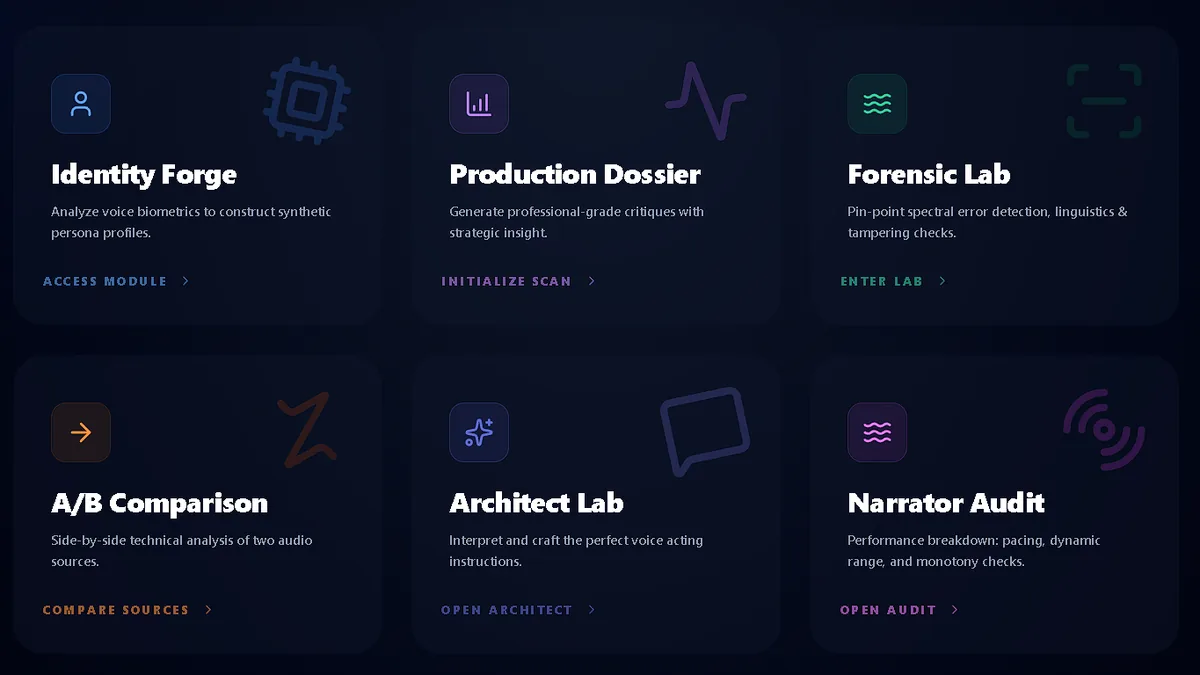
The complete production layer. From script to mastered output — human-directed, AI-powered. Not a wrapper. Not a chatbot. A production operating system for spoken audio that solves the post-production gap between AI-generated audio and publishable content.
Podcast Automation
Title to publication-ready episode in 4–6 minutes. Script generation, audio generation, forensic audit, social media clips, shorts video, Auphonic mastering — fully automated end to end.
AI Audio Auditor
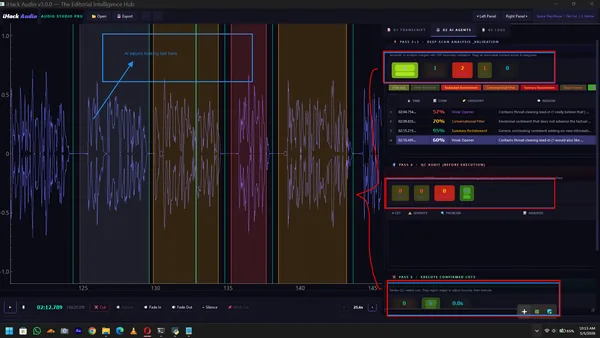
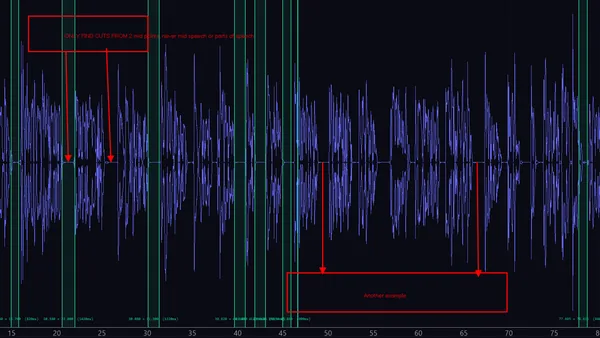
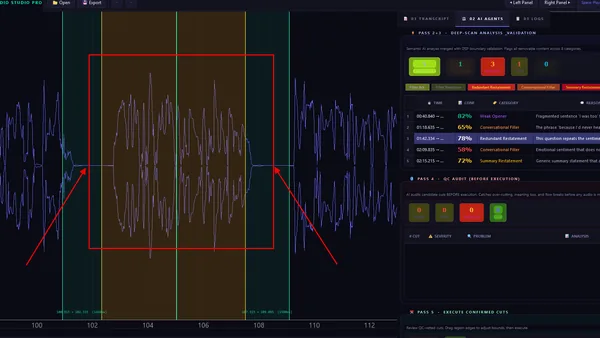
Contextual audio editing that asks "does this sound natural to a human listener?" — not "is the timestamp technically correct?" Whisper transcription → word-level timestamps → VAD segmentation → Gemma semantic analysis → editorial validation → correction.
Script Director + Jojo
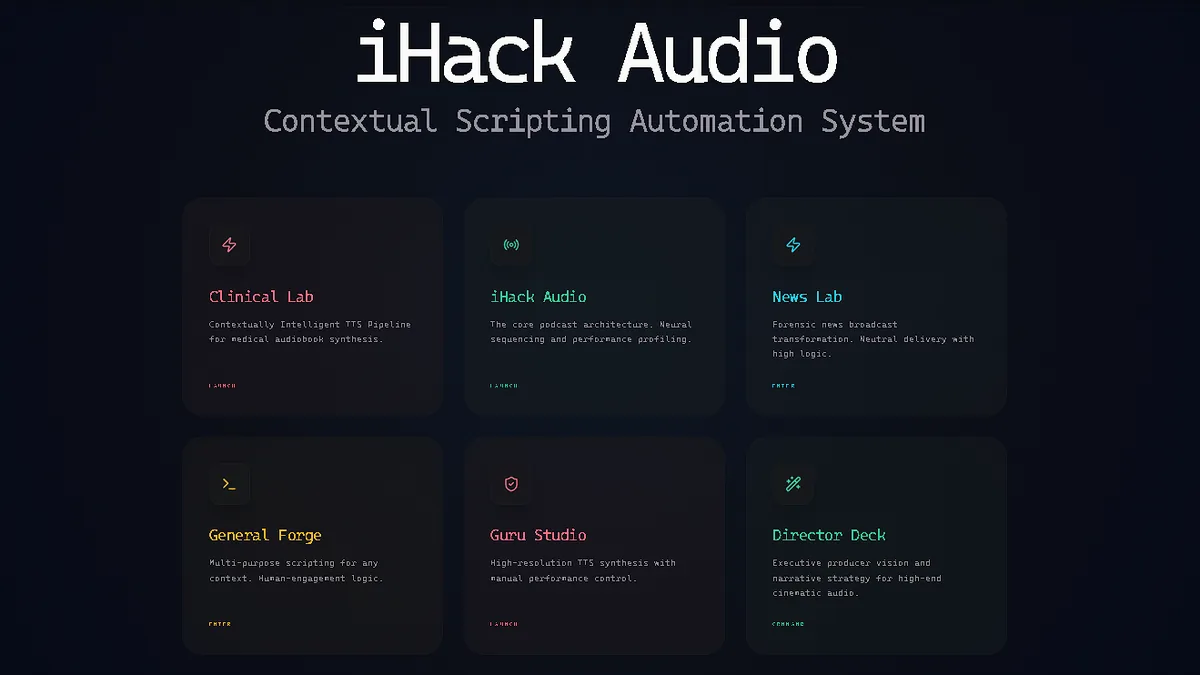
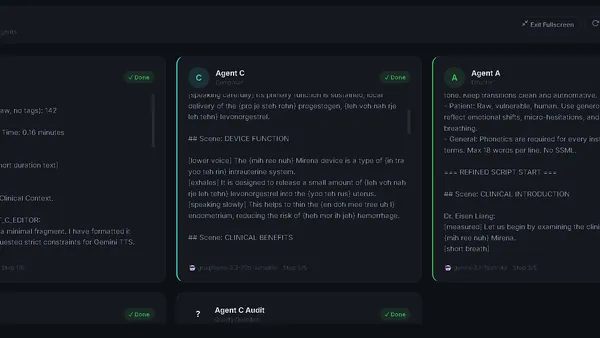
Multi-mode scripting system with a proprietary kinetic notation — [Archetype, Intensity, Stage] ((Kinetic Actions)) — that engineers vocal performance at the instruction level. Combined with Jojo, the voice-native controller that operates the entire application by speech.
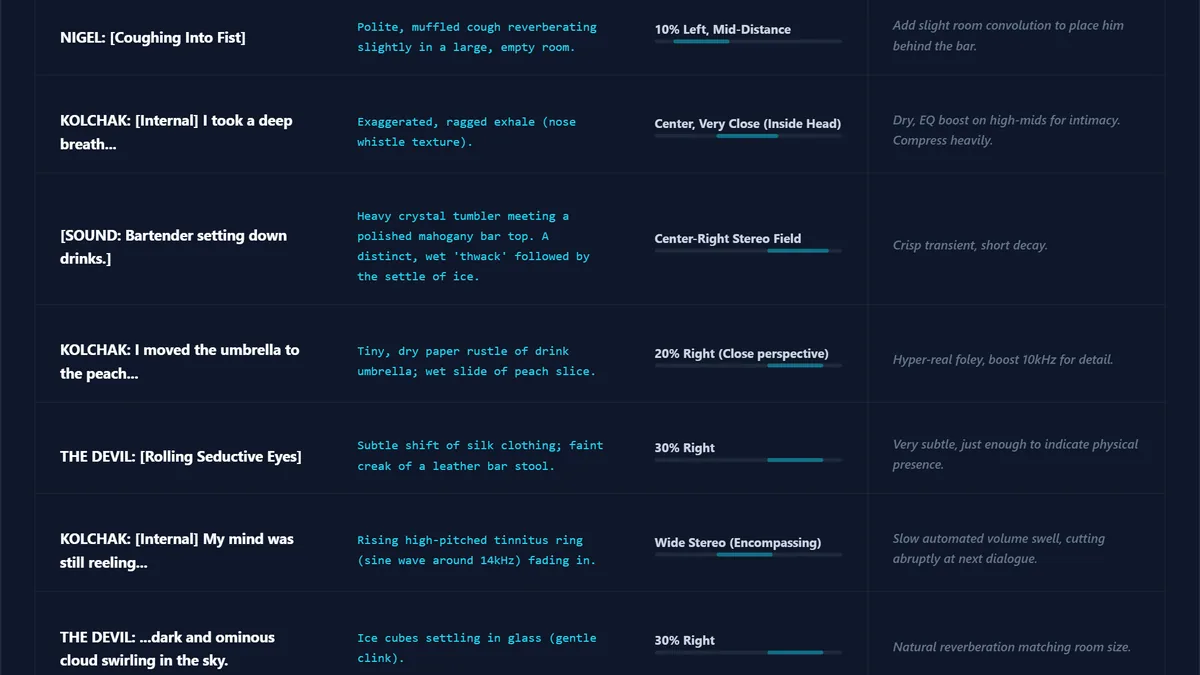
3D Spatial Map Engine
Line-by-line spatial audio design targeting A24 / Dolby Atmos standards. Ambient bed specification, SFX placement with stereo field coordinates, transition design, music recommendation by emotional arc, mixing notes per element.


Voice Cloning + Synthesis
High-fidelity voice cloning from just seconds of audio. Our model captures unique vocal signatures to generate new speech that is indistinguishable from the original. Perfect for dynamic content, character voices, and personalized audio experiences. Listen to a sample below.
Forensic Audit Lab
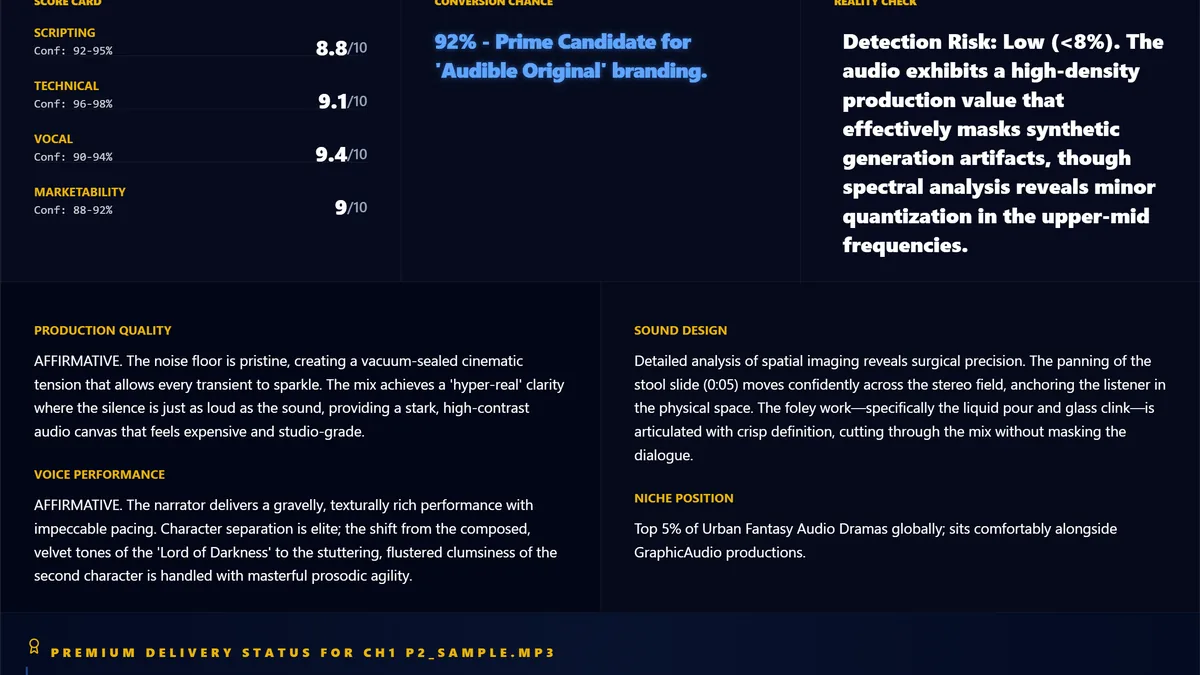
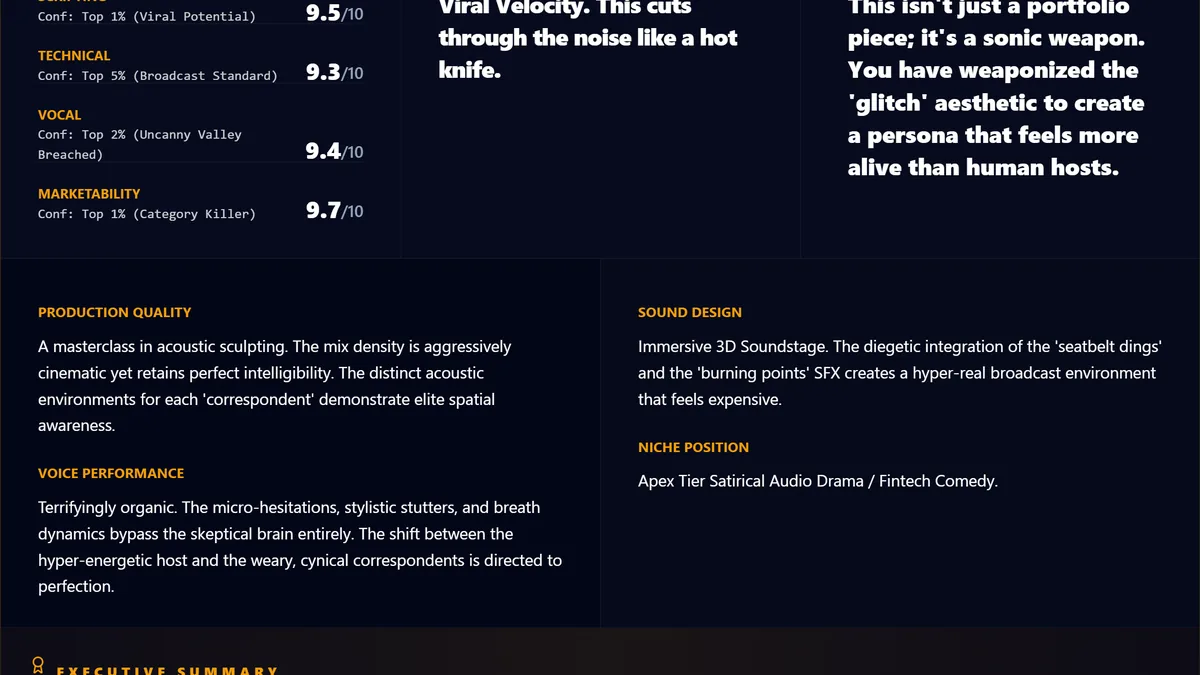
Create your character. Analyze how your character performs. Forensic audits that score every dimension of vocal performance — scripting, technical quality, vocal presence, marketability — with automated scoring and actionable feedback.
Two sides to the story.
This is the architect's lab. Time to see the human side.